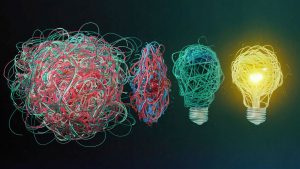
Everyone talks about data today as if it represented some sort of treasure buried within each organization, but raw data is most of the time unusable as it is. To use a metaphor, it is like comparing a rough diamond, just extracted from a mine, to the most magnificent precious stone. The real value is in information, i.e. in trustworthy data interpreted with a business context. And to be able to transform raw data into insightful information, there is no existing magic wand unfortunately. For example, thinking it is possible to jump in just one leap from an existing unfruitful data swamp to a fully-featured data lakehouse allowing the use of the latest technologies of generative AI is an illusion.
On the contrary, the path is always long and full of obstacles for organizations because it has never been possible to build castles on sand. The C-suite of lots of organizations is facing the same situation today: how to leverage our existing “data stack” in order to extract valuable and actionable insights or to obtain productivity gains thanks to modern data analytics or machine learning tools and solutions? And what will happen if our competitors are able to do it better than us in the coming months?
Most vendors offer brilliant off-the-shelf solutions with the promise of being able to leverage latest LLM technologies but they generally forget to specify that organizations need first to ensure they can totally trust their data. In the best case, they simply mention this major constraint but don’t insist on it too much as if it was the easiest part of the story. But it is not, of course.
Based on a selection of the best articles written by practitioners around the world, the aim of this blog is to highlight the most important insights that organizations should have in mind in order to implement a successful data strategy and deliver effective data-driven customer experiences.